Daily Digest — 2026-09-12
25 newsletters today.
In this digest
- Abandoned Futures — Project Timberwind / SNTP: The Particle-Bed Nuclear Rocket That Would Have Given SDI a Reusable Orbital Tug in 1993, and Got Cancelled Six Months Before Its First Reactor Test
- Daily Automotive Engines — Oil Catch Cans and Air-Oil Separators: Capturing PCV Mist Before It Fouls Your Intake
- Daily Debugging Puzzle — C's volatile Thread-Safety Trap: The Keyword That Prevents Caching, Not Races
- Daily Digital Circuits — 4:2 Compressors: How Hardware Reduces Four Numbers to Two in a Single Gate Delay
- Daily Electrical Circuits — Current Conveyors: The Forgotten Analog Building Block
- Daily Engineering Lesson — Transient Voltage Suppression Diodes (TVS): Silicon Clamps That React in Picoseconds
- Forgotten Books — The 1827 Case Against Copy-Paste Medicine
- Forgotten Darkroom — The Lost Trade of Mining Gold from Photographs
- Forgotten Patent — Ralph Teetor's "Speed Control Device": The 1945 Patent a Blind Engineer Filed to Cure Motion Sickness — and the Ancestor of Every Cruise Control, Adaptive Cruise, and Tesla Autopilot
- Daily GitHub Zero Stars — AngHelll/bdd-pilot
- Daily Hardware Architecture — 3D V-Cache and Cache Stacking: How CPUs Grew a Second Story
- Hacker News Deep Cuts — Restrictions on Geographic Data in China
- HN Jobs Teardown — Paystand: What Their Hiring Reveals
- Daily Low-Level Programming — ARM's DMB, DSB, and ISB Barriers: Three Instructions Because One Isn't Enough
- RFC Deep Dive — RFC 1127: A Perspective on the Host Requirements RFCs
- Stack Overflow Unanswered — ARM MTE synchronous mode: what does "store must complete tag check before next store executes" mean?
- Daily Software Engineering — The Hedged Request Pattern: Trading Extra Load for Better Tail Latency
- Tool Nobody Knows — bup: Git's Packfile Format as a Backup Engine, With Rolling Checksums for Sanity
- What If Engineering — What If We Built a Skyscraper-Sized Vortex Ring Generator to Punch a Hole Through Smog Over a Megacity?
- Wikipedia Rabbit Hole — Kinetic energy recovery system
- Daily YT Documentary — Living in Saba | How Life Works on an Island with Almost No Flat Land | 4K Travel Documentary
- Daily YT Electronics — I Built a Portable Dremel for Just $2! 🔥 Full Build & Test | DIY Mini Rotary Tool – Part 2
- Daily YT Engineering — Patterned Steel: The Damascus Metallurgy
- Daily YT Maker — Laser Cutting a Roll-Top Wooden Box | ForgePrint 3D
- Daily YT Welding — I Made a Teddy Bear Name Plate for Sofia | Inkscape + ArcDroid CNC Plasma
Abandoned Futures
Project Timberwind / SNTP: The Particle-Bed Nuclear Rocket That Would Have Given SDI a Reusable Orbital Tug in 1993, and Got Cancelled Six Months Before Its First Reactor Test
2026-09-12
In 1987, the Strategic Defense Initiative Organization quietly funded a black program called Timberwind. The goal: a nuclear thermal rocket with ten times the power density of NERVA, small enough to fit in a Shuttle payload bay, capable of hauling Brilliant Pebbles interceptors from LEO to any orbit in hours. The technology was particle-bed reactor (PBR) propulsion, invented at Brookhaven National Laboratory by James Powell in the early 1980s.
The trick was the fuel form. Instead of NERVA's monolithic graphite fuel elements (which cracked, eroded, and limited operating temperature to about 2,500 K), Powell's design used millions of uranium fuel microspheres, each about 500 microns across, coated in zirconium carbide. Hydrogen propellant flowed radially inward through a porous frit into the bed, absorbing heat directly from the enormous surface area of the particles, then out through a central hot channel to the nozzle.
The performance numbers were extraordinary:
- Specific impulse: 930–1,000 seconds (vs. NERVA's 850, chemical LH2/LOX's 450)
- Power density: 40 MW per liter of core (NERVA managed about 4)
- Thrust-to-weight ratio: 25–30 (NERVA was ~4; the RL-10 is ~50 but at a third the Isp)
- Core diameter under one meter, mass under two tons for a 1,000 MW engine
In 1991 the program was declassified, renamed Space Nuclear Thermal Propulsion (SNTP), and transferred to the Air Force Phillips Laboratory. Roughly $200–$800 million had already been spent (numbers still contested). Fuel elements had been tested in the Annular Core Research Reactor at Sandia. A full ground-test reactor called PIPE (Particle-bed reactor Integral Performance Element) was being fabricated at the Nevada Test Site's Saddle Mountain facility. First hot-fire was planned for 1994.
Then the Cold War ended. Brilliant Pebbles was cancelled in 1993. Without an SDI mission, the Air Force couldn't justify a rocket engine whose only civil customer was a Mars program that didn't exist. Congress zeroed the budget in FY1994. The fuel bed hardware was shipped to storage. Test-stand construction stopped mid-pour.
Why 2026 changes the math:
- HALEU is now a commodity. High-Assay Low-Enriched Uranium (up to 19.75%) sidesteps the weapons-grade issue that shadowed Timberwind's 93%-enriched HEU. Centrus Energy delivered the first US commercial HALEU in 2023.
- TRISO fuel is proven. The DOE's AGR-2 tests demonstrated coated-particle fuel operating at 1,800 K with zero cladding failures — validating exactly the microsphere concept Timberwind pioneered.
- DARPA's DRACO program (2023, BWX Technologies + Lockheed) is building a flight-test NTR for 2027. Its engine architecture is a lineal descendant of SNTP: HALEU, ceramic-coated particles, hydrogen propellant.
- Additive manufacturing now produces the porous frit and complex hot-frit geometries that were the single hardest fabrication challenge in 1991.
- Ceramic matrix composites (SiC/SiC) allow structural components at 1,900 K that Inconel-era Timberwind couldn't use.
The result is that a modernized PBR could probably hit the 1,000-second Isp target Timberwind promised, with better safety margins and civilian-legal fuel. A reusable nuclear tug moving 40 tons from LEO to lunar orbit in 30 days — the exact capability NASA now needs for Artemis logistics — sits within reach of 1993 hardware plus 33 years of materials science. The engine was cancelled not because it didn't work, but because the war it was built for ended.
Daily Automotive Engines
Oil Catch Cans and Air-Oil Separators: Capturing PCV Mist Before It Fouls Your Intake
2026-09-12
Your PCV system pulls crankcase blow-by back into the intake to burn it. Problem: those vapors carry oil mist, aerosolized by the crank whipping through the sump and by hot gases venting past the rings. On a port-injected engine, injector spray washes intake valves clean of oil deposits. On a direct-injected engine, there's no fuel wash on the back of the intake valve — that oil bakes into carbon crust, choking airflow and killing power. This is why a 60,000-mile GDI engine often needs walnut-shell blasting.
An oil catch can (or air-oil separator, AOS) sits inline between the PCV port on the valve cover and the intake manifold. Its job: slow the vapor stream, force phase separation, drop liquid oil to a reservoir, and pass clean vapor downstream.
Three separation mechanisms are used, often stacked:
- Impaction baffles — vapor hits vertical plates; heavier oil droplets have too much inertia to follow the airflow around them and stick. Cheap and effective for coarse mist.
- Cyclonic separation — the inlet enters tangentially, spinning the flow. Centrifugal force throws oil to the wall where it drains down. Works great for droplets above ~10 microns.
- Coalescing media — stainless mesh or sintered bronze catches sub-micron mist, letting tiny droplets merge into big ones that gravity can drop. Essential for a "true" AOS.
Real-world example: A 2015 VW EA888 2.0T (direct injection) with a factory PCV that separates poorly. Owners routinely find a tablespoon of oil per 1,000 miles in an aftermarket catch can. Skip it and by 80k miles you're pulling the head or paying $600 for walnut blasting. Mishimoto and Radium sell dual-can setups (one on each PCV leg — one for cruise vacuum, one for boost) that solve this permanently.
Rule of thumb — sizing the can: internal volume should be at least 10× your engine's blow-by flow rate per second. A healthy 2.0L engine passes roughly 1–2 CFM of blow-by (about 0.5–1 liter/second). So a 250–500 ml can gives enough residence time (~0.5 seconds) for droplets to fall out. Undersize it and vapor rockets straight through, useless.
Watch out: a catch can is not a delete. It must still vent to the intake — plumbing it to atmosphere causes crankcase pressure buildup, oil leaks past the rear main, and fails emissions. Also: drain it. A full can gets sucked into the intake in one gulp, hydrolocking risk on cold starts.
Daily Debugging Puzzle
C's volatile Thread-Safety Trap: The Keyword That Prevents Caching, Not Races
2026-09-12
This program launches two threads that each increment a shared counter one million times. The variables are marked volatile so the compiler won't stash them in registers. The final count should be exactly 2,000,000.
#include <pthread.h>
#include <stdio.h>

volatile long counter = 0;
volatile int  done    = 0;

static void *worker(void *arg) {
    for (int i = 0; i < 1000000; i++) {
        counter++;          /* shared, but "volatile" — safe, right? */
    }
    done = 1;               /* signal completion to a watcher thread */
    return NULL;
}

int main(void) {
    pthread_t t1, t2;
    pthread_create(&t1, NULL, worker, NULL);
    pthread_create(&t2, NULL, worker, NULL);
    pthread_join(t1, NULL);
    pthread_join(t2, NULL);
    printf("counter = %ld (expected 2000000)\n", counter);
    return 0;
}
Run it a few times on a multi-core box and you'll see numbers like 1348217, 1892044, 1210778. Never 2,000,000. On single-core hardware — or heavily optimized builds that happen to inline everything into one register — you might see the "correct" answer often enough to think the bug is flaky.
The Bug
volatile is a hint to the compiler, not a synchronization primitive. It tells the compiler:
- Don't cache this value in a register — re-read it from memory each access.
- Don't reorder or elide accesses to this location.
That's all. It says nothing about:
- Atomicity.
counter++compiles to load, add, store — three separate machine instructions. Two threads can interleave: both load 42, both compute 43, both store 43. One increment silently vanishes. - Memory ordering. Modern CPUs (x86-64, ARM, POWER) reorder loads and stores. A watcher thread spinning on
while (!done);might seedone == 1before it sees the writes that logically preceded it. On weakly-ordered ARM this happens routinely. - Cache coherence timing. Coherence eventually propagates, but "eventually" is not a happens-before relationship your program can rely on.
The confusion comes from Java, where volatile genuinely does provide acquire/release semantics and a happens-before edge. C's volatile was designed decades earlier for memory-mapped I/O registers on single-core systems. The name overlap is a historical accident that has cost the industry uncountable debugging hours.
The Fix
Use C11 atomics, which guarantee both atomicity and (by default) sequential consistency:
#include <stdatomic.h>

atomic_long counter = 0;
atomic_int  done    = 0;

static void *worker(void *arg) {
    for (int i = 0; i < 1000000; i++) {
        atomic_fetch_add(&counter, 1);
    }
    atomic_store(&done, 1);
    return NULL;
}
If C11 isn't available, use a mutex around the increment, or platform intrinsics like __atomic_fetch_add (GCC/Clang) or InterlockedIncrement (MSVC). Any of these produces both an atomic RMW instruction (lock xadd on x86) and the memory fences the hardware requires.
Reserve volatile for what it was actually designed for: memory-mapped hardware registers, signal handler flags of type sig_atomic_t, and setjmp/longjmp locals. Never as a substitute for synchronization.
volatile stops the compiler from optimizing away accesses — it does not make them atomic or provide any inter-thread ordering; reach for <stdatomic.h> or a mutex whenever more than one thread touches the data.
Daily Digital Circuits
4:2 Compressors: How Hardware Reduces Four Numbers to Two in a Single Gate Delay
2026-09-12
When you build a multiplier, you generate a mountain of partial products — a 32×32 multiply produces 32 rows that must all be summed. Wallace and Dadda trees reduce these rows using 3:2 counters (a.k.a. full adders): three input bits become a sum and a carry, reducing the row count by a factor of 3/2 per stage. But there's a smarter primitive: the 4:2 compressor.
A 4:2 compressor takes four bits of the same weight plus one carry-in from the neighboring column, and produces a sum, a carry-out (to the same column's next stage), and a carry to the next column. The key trick: the carry to the next column depends only on the four inputs, not on the carry-in. This breaks the horizontal ripple that would otherwise chain across the tree.
Internally it's two full adders, but the boolean structure is optimized. The classic implementation uses two XOR-3 gates on the critical path plus multiplexers for the carries. The result: a 4:2 compressor has a delay of roughly 3 XOR gates, versus 2 XOR gates for two cascaded 3:2 counters — but the compressor reduces four bits to two in one stage, while two cascaded 3:2s take two stages and add up to 4 XOR delays. Net win: fewer stages, lower depth, less wiring.
Real-world example: Intel's floating-point multipliers from the Pentium 4 onward used 4:2 compressor trees rather than pure Wallace trees. AMD's K10 FMA uses a mix of 4:2 and 3:2. ARM's Cortex-A76 multiplier is a 4:2 tree because it maps beautifully onto a regular layout — every compressor has the same footprint, so the physical design is a clean tiled array instead of the irregular jumble a Wallace tree produces.
Rule of thumb: for reducing N rows to 2:
- 3:2 counters need log1.5(N/2) stages ≈ 8 stages for 32 rows
- 4:2 compressors need log2(N/2) stages ≈ 4 stages for 32 rows
Half the depth, at the cost of ~40% more transistors per unit reduction. For any multiplier wider than 16 bits, the 4:2 wins on delay and on layout regularity, which is why it dominates modern designs.
The final two rows still need a fast carry-propagate adder — typically a Kogge-Stone or Ling adder — to produce the actual product. The compressor tree is the reduction; the CPA is the finish.
Daily Electrical Circuits
Current Conveyors: The Forgotten Analog Building Block
2026-09-12
Everyone learns the op-amp. Almost nobody learns the current conveyor, even though Sedra and Smith proposed it back in 1968 as a more general analog primitive. If you've ever needed a wideband transimpedance stage, a precision current mirror with voltage input, or a filter that runs cleanly at hundreds of MHz, the current conveyor is often a better answer than an op-amp.
A second-generation current conveyor (CCII) has three terminals: Y (high-impedance voltage input), X (low-impedance voltage output that tracks Y), and Z (high-impedance current output that mirrors the current flowing into X). The defining equations are beautifully simple:
- VX = VY (X follows Y like a buffer)
- IY = 0 (Y draws no current)
- IZ = ±IX (Z sources/sinks whatever current X is carrying)
The sign choice gives you CCII+ or CCII−. That's the entire abstraction.
Why bother? Op-amps have a fixed gain-bandwidth product — push voltage gain up and bandwidth collapses. Current conveyors don't. Their gain is set externally by an impedance ratio, and the internal signal path is current-mode, so parasitic node capacitances don't roll off the transfer function the same way. A CCII-based transimpedance stage can hit hundreds of MHz where an op-amp version dies at 10 MHz.
Concrete example — voltage amplifier. Tie Y to your input, put R1 from X to ground, and R2 from Z to ground with the output taken at Z. Since VX = Vin, the X-terminal current is IX = Vin/R1. That current is conveyed to Z, developing Vout = IZ·R2 = Vin·(R2/R1). Same gain formula as a non-inverting op-amp — but with no gain-bandwidth trade-off.
Rule of thumb: if your desired gain × required bandwidth exceeds ~50% of your op-amp's GBW, reach for a current conveyor (AD844 is the classic, and it also exposes the Z node explicitly — many "CFA" op-amps are secretly CCII+ blocks with a buffer). Typical AD844 achieves 60 MHz at a gain of 10, versus a general-purpose op-amp with 10 MHz GBW that would give you only 1 MHz.
Watch out for: X-terminal input impedance isn't truly zero (typically 50 Ω on the AD844), so at low R1 values it eats into your gain accuracy. Also, Z-terminal parasitic capacitance sets your ultimate high-frequency pole — keep the Z node's load light and its wiring short.
Daily Engineering Lesson
Transient Voltage Suppression Diodes (TVS): Silicon Clamps That React in Picoseconds
2026-09-12
A TVS diode is a purpose-built silicon device that clamps voltage spikes by breaking down into avalanche conduction the moment the line exceeds its rated voltage. Unlike MOVs, which use metal-oxide grain boundaries and degrade with every hit, TVS diodes are solid-state PN junctions that respond in under a picosecond and survive millions of surge events without measurable wear — as long as you stay under their peak pulse power rating.
They come in two flavors:
- Unidirectional — one PN junction, conducts normally in reverse only. Used on DC rails where polarity is fixed (e.g., a 12V automotive supply). Forward-biased, it looks like a regular diode at ~0.7V.
- Bidirectional — two junctions back-to-back, clamps in either polarity. Used on AC lines, differential data pairs (USB, CAN, RS-485), and antenna inputs where signals swing above and below ground.
Three voltages define every TVS:
- VRWM (reverse working voltage) — the highest normal operating voltage. Below this, the diode is invisible (leakage in microamps).
- VBR (breakdown voltage) — where avalanche begins, typically 10–15% above VRWM.
- VC (clamping voltage) — the actual voltage across the diode at peak surge current. This is what your downstream circuit sees, and it's always higher than VBR.
Real-world example: Protecting a CAN transceiver on an automotive ECU. The CAN bus normally swings between 0V and 5V, but load-dump events can inject ±100V transients from the alternator. A bidirectional TVS like the PESD1CAN (VRWM = 24V, VC ≈ 40V at 1A) sits across CAN_H-to-ground and CAN_L-to-ground. Under normal signaling, the diode's ~5pF capacitance is low enough not to distort the 1 Mbps signal. During a transient, it dumps the surge current to ground before the transceiver's 40V-rated input pins see anything they can't survive.
Rule of thumb — sizing peak pulse power: The IEC 61000-4-5 standard tests with an 8/20µs surge waveform (8µs rise, 20µs to half-peak). For that pulse, use PPP = VC × IPP. If your line sees 30A surges and the diode clamps at 40V, you need at least 1200W of peak pulse power capability. A 600W TVS will fail open (or shorted, then explode) on the first real strike.
The capacitance tradeoff: TVS junction capacitance ranges from ~0.5pF (specialized RF/high-speed data) to ~10,000pF (bulk power rails). On a USB 3.0 line at 5 Gbps, anything over 1pF causes eye-diagram distortion. On a 12V DC input, 500pF is fine and actually helps filter noise.
Forgotten Books
The 1827 Case Against Copy-Paste Medicine
2026-09-12
Book: The veterinary surgeon or, Farriery taught on a new and easy plan by John Hinds (1827)
Read it: Internet Archive
Nearly two centuries before "evidence-based medicine" became a slogan, a London farrier named John Hinds wrote a preface that reads like a manifesto against what we would today call cargo-cult practice. In his 1827 treatise on horse diseases, Hinds warned readers not to trust the fashionable recipe books of his day — including, presumably, his own — unless they first understood why a remedy worked.
Indeed, he should study it hard, if he would become proficient in "the Art of Farriery," and not rely implicitly upon other people's prescriptions for the cure of any alleged disorder, which have been composed for the most part without any such preparation. From this neglect, also, symptoms of one disorder are confounded with those of another, when the proposed remedies cannot possibly effect the cure.
His prescription for genuine competence was startlingly direct: cut open dead horses. Whenever, and wherever, you can.
He had best to comply with the advice strenuously urged at the very outset, to examine the internal parts of dead horses, as often as opportunity presents itself, which in the neighbourhood of large towns and hunts is frequent enough. For this is the manner in which I was myself mainly instructed.
What's remarkable here is not the recommendation of dissection — anatomists had been doing it for centuries — but Hinds's insistence that the working farrier, the ordinary shoeing-smith or groom, had a moral obligation to develop his own diagnostic eye rather than mechanically match symptoms to recipes in a book. He was writing at the very moment veterinary medicine was professionalizing (the Royal Veterinary College had opened in 1791), and the market was flooded with "quack" pamphlets promising cures. His response was to tell readers, in effect: your book is only as good as your ability to see through it.
Modern medicine has spent the past thirty years rediscovering the same tension. Clinical decision-support systems, protocol-driven care, and now large language models can all produce a plausible answer for any set of symptoms. But study after study finds that the practitioners who catch the outliers — the atypical presentations, the two-diseases-at-once cases — are the ones who understand pathophysiology deeply enough to distrust the pattern-match. Physicians call this the difference between "System 1" and "System 2" thinking. Hinds called it the difference between studying nature and copying prescriptions.
His observation that "symptoms of one disorder are confounded with those of another" when the remedy is applied without understanding is essentially a description of diagnostic anchoring bias, first named in the medical literature in the 1970s. Hinds had no framework for cognitive bias. He just watched a lot of horses die from correctly-applied wrong cures.
The advice to walk down to the knacker's yard and open up a corpse is quaint. The underlying claim — that reading recipes is not the same as understanding disease — is not.
Forgotten Darkroom
The Lost Trade of Mining Gold from Photographs
2026-09-12
Book: The reducer's manual, and gold and silver worker's guide, being a complete, practical hand-book on the saving and reduction of every class of photographic wastes, and gold and silver residues by Victor G. Bloede (1867)
Read it: Internet Archive
In 1867, a young chemist named Victor G. Bloede — "Late Assistant Chemist at the Cooper Institute" — published a book aimed at a profession that no longer exists. His subject: how to systematically recover the gold and silver dissolved into every photograph made in the 19th century.
The table of contents reads like a forgotten industrial workflow:
On the Best Methods and Apparatus for Saving the Various Wastes Occurring in Photography — The Bath — The Sensitized Plate — Developer Residues — The Fixing Solution — Old Negatives, Ambrotypes, etc., etc — Paper Clippings, etc., etc — The Print Washings — The Toning Solution — The Print Fixing Solution
Every step of the wet-plate collodion process leaked precious metal. Silver nitrate soaked the plate; gold chloride toned the print; both metals drifted into the fixing bath, the wash water, and even the paper clippings on the darkroom floor. Bloede taught photographers and dedicated "reducers" how to burn, roast, precipitate, decant, and smelt these residues back into ingots — a whole chapter is devoted to "The Furnace and the Management of Heat — Selection and Preparation of Fuel — Crucibles and Melting Pot."
Was this real money? Absolutely. A working portrait studio in the 1870s could recover several ounces of silver per month from its fixing baths alone. Refiners paid cash for barrels of exhausted hypo. Some studios employed the reducer's trade themselves; others sold their sludge to specialists. The economics were plain: silver was expensive, and every unfixed photograph literally rinsed money down the sink.
What killed the trade? Three things: gelatin dry plates reduced silver consumption, electrolytic recovery replaced smelting, and finally digital photography erased silver halide chemistry from consumer life entirely. The knowledge Bloede so carefully compiled — how to precipitate a toning bath, how to burn paper wastes to concentrate their metal, how to manage a crucible fire — became irrelevant within a century.
Except it didn't, really. The modern analogue is urban mining — recovering gold, silver, palladium, and rare earths from discarded circuit boards, catalytic converters, and X-ray film. The techniques Bloede describes (roasting, precipitation with iron or zinc, cyanide leaching, cupellation) are still the backbone of e-waste refining. A ton of smartphone motherboards contains more gold than a ton of gold ore. The Bureau of Mines rediscovered in the 1980s what Bloede's readers knew in 1867: your waste stream is an ore body if you know how to read it.
Hospitals still recover silver from X-ray fixer. Dental labs still smelt gold from crown scrap. But the household-scale knowledge — that a working professional could and should reclaim their own precious metals — is gone. Bloede's readers would be astonished at how much silver and gold we now simply throw away.
Forgotten Patent
Ralph Teetor's "Speed Control Device": The 1945 Patent a Blind Engineer Filed to Cure Motion Sickness — and the Ancestor of Every Cruise Control, Adaptive Cruise, and Tesla Autopilot
2026-09-12
Ralph Teetor lost his sight at age five in a workshop accident. He never learned to drive a car. And yet, in August 1950, the U.S. Patent Office granted him US Patent 2,519,859, "Speed Control Device for Resisting Operation of the Accelerator" — the mechanism that would become cruise control, and, seventy-five years later, the throttle backbone of every self-driving car on the road.
Teetor filed the application in 1945. He was chief engineer at Perfect Circle Corporation, an Indiana piston-ring maker, and had developed a mechanical intuition sharp enough that colleagues said he could diagnose an engine by ear alone. The origin story is unusually specific: Teetor was regularly chauffeured by his patent attorney, a man who unconsciously sped up while talking and slowed down while listening. The rocking motion made Teetor carsick. He decided to invent his way out of it.
The patent describes a beautifully simple closed loop. A cable driven off the transmission spins a small centrifugal governor. As road speed rises, flyweights fling outward and push against a diaphragm connected to engine vacuum. That vacuum, in turn, pulls a pneumatic servo attached to the throttle linkage. Set a target speed, and the governor fights any deviation — the throttle backs off when the car accelerates downhill, and opens when it lugs uphill. Teetor called it the Speedostat.
Chrysler licensed it. The 1958 Imperial shipped it as "Auto-Pilot." Cadillac adopted it a year later under the name that stuck: Cruise Control. Within a decade it was standard equipment across the American luxury market.
The modern lineage is direct and largely unbroken.
- Adaptive Cruise Control (ACC) — Mitsubishi shipped the first radar-based ACC in Japan in 1995; Mercedes followed with Distronic in 1999. Both are Teetor's control loop with an extra input: measured distance to the car ahead becomes another variable the governor tries to hold.
- Tesla Autopilot and every Level 2+ ADAS system — internally called "Traffic Aware Cruise Control," the throttle-and-brake half of Autopilot is architecturally Teetor's PID loop, now closed around camera and radar fusion instead of a spinning cable.
- Waymo, Cruise, Mobileye — the module every autonomy stack labels "longitudinal control" is a lineal descendant. Sensors and target-setting have exploded in complexity; the actuator loop underneath still does what Teetor's governor did.
- EV one-pedal driving — the regenerative-braking algorithms that hold speed on a downhill in a Rivian or a Model Y are a Teetor governor in software, blending motor torque instead of vacuum.
Teetor's insight was not the mechanism — centrifugal governors dated back to James Watt's steam engines in 1788. His insight was applying feedback control to the driver's own foot, treating the human as a noisy signal to be smoothed rather than a system to be replaced. That framing — augment the driver, don't remove them — is exactly the posture Tesla, GM Super Cruise, and Ford BlueCruise all still take in 2026, half a century into the arc.
Teetor served as president of the Society of Automotive Engineers in 1936. He held more than forty patents. He never once operated the invention he is remembered for.
Daily GitHub Zero Stars
AngHelll/bdd-pilot
2026-09-12
Language: TypeScript
Among a sea of randomly-named repos with cryptic six-letter identifiers, bdd-pilot stands out as one of the few in this batch with a real name, a real language tag, and — judging by the naming — a real intent. The name suggests a Behavior-Driven Development pilot: a TypeScript project likely exploring how BDD workflows can be automated, assisted, or "piloted" (perhaps with an AI copilot flavor, given the current zeitgeist).
BDD tooling in the TypeScript ecosystem has historically been a bit fragmented. Cucumber.js exists, and playwright-bdd has gained traction, but the developer experience of writing Gherkin scenarios, wiring up step definitions, and keeping them in sync with evolving application code remains tedious. A "pilot" project in this space could plausibly tackle any of several pain points:
- Scaffolding — generating step definitions from feature files automatically
- Sync detection — flagging orphaned steps or missing implementations
- AI-assisted authoring — turning natural-language requirements into runnable scenarios
- Integration glue — bridging BDD frameworks with Playwright, Vitest, or Jest
Even at zero stars and with no description, the repo is worth a peek because BDD tooling is one of those areas where anyone shipping a genuinely useful helper can gain traction fast. The QA and test-automation community actively hunts for tools that reduce the friction between product requirements and executable specifications.
Who might benefit? QA engineers evaluating BDD adoption, test automation leads working with Cucumber or Playwright, and developers curious about how AI-assisted test authoring is evolving in TypeScript-heavy codebases. It's also a nice reference point for anyone considering building their own BDD tooling — early-stage repos often reveal cleaner architectural decisions before feature creep sets in.
Daily Hardware Architecture
3D V-Cache and Cache Stacking: How CPUs Grew a Second Story
2026-09-12
For decades, CPU caches lived on the same silicon die as the cores, competing for area with everything else. 3D V-Cache (AMD's marketing name; the technique is hybrid bonding or TSV stacking) breaks that constraint by bonding a second silicon die directly on top of the CCD, tripling L3 capacity without touching the core layout.
The trick: through-silicon vias (TSVs) punch vertical connections through the base die to a cache-only die stacked above. AMD's implementation uses direct copper-to-copper hybrid bonding (no solder bumps), giving inter-die bandwidth similar to on-die wires. The stacked SRAM die adds 64MB of L3 on top of the 32MB base, yielding 96MB total per CCD.
Why stacking, not just a bigger die?
- Wafer yield: SRAM has huge, regular structures — much higher yield per mm² than logic. Fabricating cache separately on an optimized process avoids dragging down CPU yield.
- Wire length: A 96MB planar L3 would require signals to traverse a much larger die area, adding latency. Vertical stacking keeps wires short.
- Thermal reality: SRAM sits above the cores — but SRAM generates almost no heat compared to logic. It insulates the hot cores from the heatspreader, forcing AMD to lower peak clock speeds on X3D parts by ~200-400 MHz.
Real-world impact: The 7800X3D beats the 7700X in gaming by 15-30% despite lower clocks, because game code often has a working set that fits in 96MB but not 32MB. Factorio's late-game simulation improves ~70%. Meanwhile, compilation workloads (which stream through memory rather than reuse hot data) gain almost nothing and lose to the non-X3D chip because of the clock deficit.
Rule of thumb: If your working set W satisfies 32MB < W < 96MB and access patterns show temporal reuse, expect V-Cache speedups of 15-40%. If W < 32MB (fits in base L3) or W >> 96MB (streams through both), expect zero benefit and a small clock-driven regression.
Latency cost: The stacked L3 adds ~4 cycles vs. the base L3 (from ~46 to ~50 cycles on Zen 4), because addresses must be hashed across a larger slice count and signals traverse TSVs. AMD hides this by keeping the base 32MB as the "fast" region for hot data, essentially creating an L3.5.
Intel's competing approach — Foveros — stacks logic-on-logic (used in Meteor Lake's compute tile atop the base tile), a harder thermal problem but more flexible than cache-only stacking.
Hacker News Deep Cuts
Restrictions on Geographic Data in China
2026-09-12
Link: https://en.wikipedia.org/wiki/Restrictions_on_geographic_data_in_China
HN Discussion: 1 points, 0 comments
This Wikipedia article covers one of the most bizarre and technically fascinating regulatory regimes in modern software: China's legal requirement that all maps published within its borders use a deliberately obfuscated coordinate system called GCJ-02 (colloquially "Mars Coordinates"). If you've ever wondered why your GPS pin appears in the middle of a river when you cross into mainland China, this is the reason.
The short version: China treats accurate geographic survey data as a state secret. WGS-84 coordinates — the global standard used by every consumer GPS device — are illegal to publish for locations inside the PRC. Instead, licensed mapping providers must apply a nonlinear, pseudo-random offset algorithm that shifts every point by roughly 50–500 meters in an unpredictable direction. The algorithm itself is classified, though it has been reverse-engineered and reimplemented in open-source libraries.
Why a technical audience should care:
- It's a case study in state-mandated data corruption. Unlike encryption, which preserves information for authorized parties, GCJ-02 is a lossy transformation deliberately designed to degrade a public dataset. Every Chinese mapping product silently ships with the offset baked in.
- It breaks everything. Overlaying a WGS-84 GPS track on a Chinese map (Baidu, Amap, etc.) produces visible drift. Baidu actually adds a second offset on top of GCJ-02, called BD-09, requiring a two-step conversion.
- The reverse-engineering story is great. Researchers determined the offset function is deterministic — same input always yields the same output — which means it isn't really a secret anymore. Libraries like
eviltransformandcoordtransformconvert freely between the systems. - It has real geopolitical stakes. Foreign companies operating in China face liability if they publish "correct" coordinates. This has shaped how Apple Maps, Google Maps, and every ride-hailing app handle the mainland.
The article also touches on the survey-data licensing regime, the criminal penalties for unauthorized surveying (drone hobbyists have been prosecuted), and how the rules extend to satellite imagery resolution limits. For anyone working on geospatial software, autonomous vehicles, logistics, or just curious about how sovereignty gets encoded into coordinate systems, this is essential background reading — and it's the kind of thing you can't fully appreciate until you've had a map integration mysteriously fail at the Chinese border.
HN Jobs Teardown
Paystand: What Their Hiring Reveals
2026-09-12
Source: HN Who is Hiring
Posted by: xtracto
Paystand's posting (ID: 22668620) is the most revealing on the list because it's a FinTech startup openly framing itself as a payments-rail disruptor — "like Venmo but for B2B" — while quietly telegraphing where they're actually headed technically.
The stack signal. They're hiring DevOps, Full Stack, and SDET simultaneously across two offices (Scotts Valley, CA and Guadalajara, MX). That trio is textbook "we shipped an MVP, customers are on it, and now we need to industrialize." DevOps means infrastructure pain. SDET means regression pain. Full Stack means feature pressure. All three at once means all three at once.
The strategic tell. The framing — "payment infrastructure built 50 years ago is obsolete," "intermediaries taking a cut," "moving bits and bytes like email" — is almost verbatim the pitch for blockchain-settled B2B payments. They don't say "blockchain" in the excerpt, but the analogy to email (permissionless, peer-to-peer, no per-byte fees) is the tell. Paystand is publicly known to run on a private/hybrid blockchain for settlement, and this posting is the recruiting-language version of that thesis.
What the org shape reveals:
- Guadalajara + Scotts Valley: classic nearshore engineering model. Cheaper senior talent, same time zone as CA HQ. Signals cost discipline — they're not YC-flush.
- ONSITE only: in a thread dominated by "REMOTE," this is a red flag for 2020-era candidates but a green flag for culture cohesion. They want the team physically together.
- No specific language named: unusual. Either they're stack-agnostic (unlikely for a payments company with compliance surface area) or they don't want to scare off polyglots. Suggests pragmatism over dogma.
Red flags: "Building the next generation" + missing concrete tech stack + no comp mentioned. The Venmo comparison is also a stretch — Venmo is consumer P2P; B2B payments involve invoicing, reconciliation, AR/AP integration, and regulatory weight that Venmo never touched. Marketing gloss over hard problems.
Green flags: Coherent thesis, real customers implied (they wouldn't hire SDET otherwise), dual-geography scaling, and a founder-level worldview about payment infrastructure. This isn't a "build a CRUD app" job — the person who takes it will touch settlement, compliance, and rails.
Daily Low-Level Programming
ARM's DMB, DSB, and ISB Barriers: Three Instructions Because One Isn't Enough
2026-09-12
On x86, memory ordering is mostly the CPU's problem — the TSO model means loads don't reorder past loads, and stores don't reorder past stores. On ARM, memory ordering is your problem. ARM's weak memory model will happily reorder almost anything, so ARM gives you three distinct barrier instructions with confusingly similar names.
DMB (Data Memory Barrier) orders memory accesses as observed by other observers. It doesn't wait for anything to complete — it just guarantees that memory operations before the DMB become visible to other cores before those after it. This is your workhorse for lock-free algorithms. DMB ISH (Inner Shareable) is the common flavor for multi-core coherency.
DSB (Data Synchronization Barrier) is stronger: it stalls the pipeline until all prior memory accesses have actually completed. Cache maintenance operations, TLB invalidations, and page table walks aren't finished until a DSB retires. This is why you need DSB ISH after updating a page table entry — otherwise the hardware page walker might read the old value.
ISB (Instruction Synchronization Barrier) flushes the instruction pipeline. Any instructions already fetched or decoded are thrown out and re-fetched. You need this after modifying self-modifying code, changing system registers that affect execution (like SCTLR_EL1's MMU enable bit), or updating a page table entry that maps executable code — because the instruction stream is speculatively fetched independently of the data path.
Real example — enabling the MMU:
- Write new page tables to memory
DSB ISH— ensure page tables are actually written to memory- Write SCTLR_EL1 to enable the MMU
ISB— flush the pipeline so the next instruction fetches through the MMU, not around it
Skip the ISB and you'll fetch the next few instructions with the MMU disabled, then suddenly translate — a debugging nightmare.
Rule of thumb: DMB for cross-core visibility of ordinary data (99% of lock-free code). DSB when the hardware needs to see completion (TLB, cache maintenance, DMA). ISB when the CPU's instruction stream needs to reflect the change.
The shareability domain suffix matters too: SY (full system, slowest), ISH (inner shareable, all cores in your cluster — usually what you want), NSH (non-shareable, single core, for local device MMIO), OSH (outer shareable, includes GPUs and other coherent masters). Using DMB SY everywhere works but costs 3-10× more cycles than DMB ISH on modern cores.
RFC Deep Dive
RFC 1127: A Perspective on the Host Requirements RFCs
2026-09-12
RFC 1127 is one of the most unusual documents in the RFC series: a non-normative commentary on the two normative documents that had just shipped alongside it. In October 1989, the IETF published the Host Requirements RFCs — RFC 1122 (Communication Layers) and RFC 1123 (Application and Support). These 200+ pages defined what it meant for a machine to be a conforming Internet host. RFC 1127 is Bob Braden's companion piece explaining what the working group argued about, what they punted on, and what they thought was already broken.
The problem it solved was subtle but crucial. By 1989 there were multiple vendor TCP/IP stacks in commercial deployment, and every one interpreted the ambiguous corners of RFCs 791, 792, 793, and friends slightly differently. The Host Requirements RFCs were an attempt to enumerate every subtle behavior and pick one — a "MUST/SHOULD/MAY" style specification years before RFC 2119 formalized that vocabulary. But specifications are terse and don't explain why. RFC 1127 fills in the reasoning, and it's a treasure of engineering history.
A tour of the issues Braden documented:
- The TCP urgent pointer. Two incompatible readings of RFC 793 existed in the wild: does the pointer indicate the last byte of urgent data, or the byte after it? BSD said one thing, the spec arguably said the other. The working group picked BSD's interpretation because that's what shipped. Compatibility beat correctness.
- Silly Window Syndrome. Clark's SWS avoidance was still recent enough to require careful explanation — some vendors had not implemented it.
- Path MTU Discovery. Discussed as a promising but not-yet-standard technique. It became
RFC 1191a year later and is now the load-bearing mechanism behind nearly every packet on the internet. - ICMP Source Quench. Braden noted it was already known to be ineffective as congestion control. It was formally deprecated by
RFC 6633— twenty-three years later. - IP Type-of-Service. Nobody used it correctly; nobody knew what "low delay" meant in practice. The field was eventually reclaimed for DiffServ in
RFC 2474. - Header prediction. Van Jacobson's optimization for the TCP fast path was so new that it needed explaining, not just referencing.
What makes the document quietly important today is its meta-lesson: interoperability is a social contract, not a mathematical property. The Host Requirements effort was the first large-scale attempt to say "here is every corner case, ranked by how strongly we mean it." That style — MUST/SHOULD/MAY tables, explicit robustness principle discussion, deliberate divergence between "must send" and "must accept" — became the template for every serious internet protocol spec that followed. QUIC's specification (RFC 9000) still reads like a descendant of this era.
The document is also a warning about how long deprecation takes. Source Quench, subnet-directed broadcast, and the "Class E" address block were all flagged as problems in 1989. Some of them have been solved since; others still lurk in obscure firmware. Anyone who has debugged a modern network stack has, without knowing it, fought battles Braden narrated 37 years ago.
Read it if you write network code. It's a rare glimpse of a standards body arguing honestly, in public, about what it got wrong.
Stack Overflow Unanswered
ARM MTE synchronous mode: what does "store must complete tag check before next store executes" mean?
2026-09-12
The asker is reading Arm's Cortex-A720 Software Optimization Guide and hits a deceptively simple sentence: in synchronous MTE mode, each store must complete its tag check before the next store executes. They want to know where in the pipeline "executed" lives — issue, retirement, or L1 arrival — and whether the second store can start speculatively.
Why it's tricky. Memory Tagging Extension checks a 4-bit allocation tag stored alongside each 16-byte granule against the logical tag in the pointer. In synchronous mode, a tag mismatch must raise a precise SError-like exception on the offending instruction — no store past the faulting one can become architecturally visible. That precision constraint is what forces the ordering the manual describes; the interesting question is what microarchitectural knobs Arm actually turns to enforce it.
The most likely reading. "Executed" here is Arm's optimization-guide shorthand for dispatched down the store pipe to the point where the tag lookup resolves, not full retirement and not L1 write. Concretely:
- Stores can still be issued out of order — the ROB doesn't stall on issue.
- But the AGU/store-address path serializes at the tag-check stage: store N+1's tag check cannot start (or at least cannot resolve) until store N's is known good. Otherwise a fault on N could be reported alongside side effects of N+1, breaking preciseness.
- Retirement of the store to the store buffer / L1 happens later and is not the gating point the guide is talking about — that's why sync mode is slower per-store but not catastrophically so.
Direction toward a solid answer. Point the asker at three sources: (1) ARM ARM section on MTE Tag Check Fault reporting modes (synchronous vs. asynchronous vs. asymmetric); (2) the A720 TRM, which describes the store pipe stages; and (3) Arm's MTE whitepaper, which explicitly contrasts sync ("precise, serialized at the store pipe") with async ("checks accumulate in TFSR, no ordering"). The gap between "architectural retirement" and "the check completes" is the crux — sync mode couples them at the tag-check stage but not at cacheline write.
Gotchas worth flagging.
- Loads behave differently: sync-mode load tag checks resolve before the load's result is forwarded, so speculative use of a mistagged load is blocked at the consumer, not by serializing the load pipe.
- Asymmetric mode (sync loads, async stores) exists precisely because store serialization is the expensive part — evidence that the store-pipe check is the bottleneck.
- Microarchitectural details differ between A720, A715, X4, etc. — the guide's wording is Arm's contract with the compiler writer, not a promise about a specific stage number.
Daily Software Engineering
The Hedged Request Pattern: Trading Extra Load for Better Tail Latency
2026-09-12
Your p50 latency is 20ms. Your p99 is 800ms. That p99 isn't a network problem or a slow query — it's the tail. One replica is doing GC, another is on a noisy neighbor VM, a third is finishing a background compaction. On any given request, most replicas are fast, but the one you happened to pick might be having a bad day.
Hedged requests attack this directly: fire the request to replica A, wait a short delay, and if you haven't heard back, fire the same request to replica B. Take whichever response arrives first, cancel the other.
Google's The Tail at Scale paper reports that a 5% hedge (send the backup after the p95 latency) can cut p99 latency by 40x while adding only ~5% extra load. That's the trade: a small, tunable amount of duplicate work in exchange for dramatically tighter tail behavior.
Concrete example. A recommendation service reads user embeddings from a 3-replica key-value store. p50 is 8ms, p99 is 250ms. Without hedging, a page that fans out to 20 embedding lookups has a ~18% chance at least one lookup hits p99 (1 − 0.99^20). With hedging fired at 15ms (the p90), that probability collapses because you'd need both the primary and backup replica to be slow — a squared probability. Extra RPC volume: about 10%.
Rule of thumb. Fire the hedge at your current p95. That guarantees hedging adds ~5% extra load in steady state (only the slowest 5% of requests spawn a duplicate), while catching every request that's about to become a tail event.
Where it works:
- Idempotent reads — safe to duplicate, easy to cancel.
- Multi-replica stores — you have somewhere else to send the retry.
- Independent failure modes — GC on one node doesn't mean GC on another. Correlated failures (a bad deploy hitting all replicas) neutralize hedging.
Where it hurts:
- Writes — unless the backend is idempotent, you'll double-apply.
- Overloaded systems — hedging adds load right when the system is struggling. Under saturation it makes tails worse. Combine with an adaptive circuit: disable hedging when queue depth exceeds a threshold.
- Uncancellable work — if the "loser" keeps running server-side, you paid for both.
Production implementations (gRPC, Envoy, DynamoDB SDK) all support hedging as a first-class knob. Turn it on for read paths, tie the delay to your live p95 percentile, and put a kill switch on it for overload scenarios.
Tool Nobody Knows
bup: Git's Packfile Format as a Backup Engine, With Rolling Checksums for Sanity
2026-09-12
Everyone's tried to abuse Git as a backup tool. Everyone's watched it explode the first time they committed a 40GB VM image — packing goes quadratic, memory blows up, and there's zero dedup across similar chunks. Meanwhile rsync gives you a mirror, not history; borg/restic work but their chunk stores are proprietary formats you'd have to reverse-engineer if the project ever died.
bup, written by Avery Pennarun around 2010, took Git's packfile format — content-addressable, extensively documented, battle-tested by every developer on earth — and bolted on a rolling-checksum chunker (the same rsync trick) so it can dedupe enormous binary files at the byte level. Every bup repo is a real git repo. In a pinch, git fsck still works on it.
bup init
bup index /var/lib/libvirt/images
bup save -n vmbackup /var/lib/libvirt/images
Run it again tomorrow after 200MB of writes inside a 40GB qcow2. bup rolls a hash across each file, finds chunk boundaries at content-defined points, and stores only the chunks it hasn't seen. A rename or a move? Zero new bytes. A 2MB edit deep inside a huge image? 2MB stored, not 40GB.
Browse and restore feel exactly like Git:
bup ls -l vmbackup/latest
bup restore -C /tmp/out vmbackup/latest/./var/lib/libvirt/images
Or mount the entire history as a filesystem — every snapshot, every version, one FUSE tree:
bup fuse /mnt/bup
ls /mnt/bup/vmbackup/       # every timestamp as a directory
Push to a remote host over ssh, no daemon required:
bup on backup-host save -n laptop $HOMEThe wizard tricks are where bup earns its keep:
- Arbitrary stream dedup:
mysqldump db | bup split -n db-dumpsstores the dump as content-addressed chunks. Tomorrow's dump reuses every unchanged chunk.bup join db-dumps/lateststreams it back. Same trick works forzfs send. - Bit-rot armor built in:
bup fsck --generatewrites par2 Reed-Solomon recovery data alongside packs.bup damageintentionally corrupts blobs so you can verify recovery works. No external tooling. - Real Git underneath:
git log --all,git gc, evengit cat-file -pon a chunk. If bup itself vanished from the internet tomorrow, your backups are still Git objects.
Watch out for:
- Metadata (ownership, xattrs, ACLs) lives in
.bupmsidecar files inside each tree. You need bup itself to restore them faithfully —git checkoutalone won't do it. bup gcexists but is still marked experimental. Historically bup was append-only; treat repos that way in production.- The index is separate from the pack store, so
bup indexbefore everybup save. Miss that step and it happily saves nothing.
Install: apt install bup, brew install bup, or dnf install bup. Python plus a small C extension for the rolling hash.
What If Engineering
What If We Built a Skyscraper-Sized Vortex Ring Generator to Punch a Hole Through Smog Over a Megacity?
2026-09-12
Delhi's winter PM2.5 routinely hits 500 µg/m³ — twenty times the WHO limit. The smog sits trapped under a temperature inversion, a 300-meter lid of warm air pressing cold, dirty air against the ground. What if we punched through it with a giant smoke ring?
Vortex rings are absurdly efficient at moving fluid over long distances. A dolphin's bubble ring holds shape for meters. Volcanic vortex rings from Etna have been tracked at 200 m altitude. The physics: a toroidal vortex carries its own low-pressure core, entraining surrounding fluid and self-propelling until viscous decay wins. Unlike a jet, which dissipates via turbulent mixing within ~10 diameters, a laminar vortex ring can travel 50-100 diameters before breaking up.
The machine: A 200-meter-diameter vertical cylinder, 500 m tall, open at the top. A piston (or pulsed fan array) at the bottom shoves a slug of air upward. As it exits the orifice, the shear layer rolls up into a torus. Aim it at the inversion layer.
Sizing the ring. Optimal vortex-ring formation number is L/D ≈ 4 (Gharib et al., 1998) — push a slug longer than that and the extra fluid trails as a jet, wasting energy. So for a 200 m orifice, piston stroke ≈ 800 m of air column. With ejection velocity U = 30 m/s, ring translational velocity ≈ 0.6U ≈ 18 m/s. It reaches the 300 m inversion in ~17 seconds.
Energy per shot. Slug volume: π(100)² × 800 ≈ 2.5 × 10⁷ m³. Mass at ρ=1.2 kg/m³ ≈ 3 × 10⁷ kg. Kinetic energy at 30 m/s: ½mv² = 1.35 × 10¹⁰ J = 3,750 kWh per ring. At $0.10/kWh, that's $375 per shot — trivial compared to Delhi's smog-related mortality costs (~$36 billion/year per Lancet).
Does it actually clear anything? Here's the beautiful part. The ring doesn't just push a hole — it entrains a coaxial column of air roughly 3× its own volume as it travels. Punching through the inversion creates a temporary chimney: warm ground-level air (buoyantly unstable once released) rushes up through the breach. One 200 m ring opens a ~600 m diameter mixing corridor for perhaps 10 minutes before the inversion re-seals.
The catch — Reynolds number. Re = UD/ν = 30 × 200 / (1.5 × 10⁻⁵) ≈ 4 × 10⁸. That's brutally turbulent. Real vortex rings at Re > 10⁵ develop azimuthal instabilities (Widnall waves) and shed vorticity chaotically. Lab-scale coherence numbers (50-100 diameters travel) collapse to maybe 2-3 diameters at these scales. So 600 m of travel, not 20 km. Still enough to breach a 300 m inversion — barely.
Structural reality. A 200 m cylinder must survive the reaction force from ejecting 3 × 10⁷ kg at 30 m/s in ~25 seconds: F = ma ≈ 3.6 × 10⁷ N, or ~3,600 tonnes of thrust. That's a Saturn V's F-1 engine, pointed downward, inside a stadium. The foundation must anchor against uplift on every reverse stroke. Manageable — offshore wind monopiles handle comparable cyclic loads.
Scaling up: Ring 20 of these around Delhi's periphery, fire in coordinated sequences during peak inversion hours. Total power draw during a firing cycle: ~500 MW — half a nuclear reactor for the world's largest cough drop.
Wikipedia Rabbit Hole
Kinetic energy recovery system
2026-09-12
Wikipedia: Read the full article
In 2009, Formula 1 introduced a rule so strange it sounded like science fiction: cars could carry a spinning glass disc inside a vacuum chamber, whirling at 64,500 RPM, storing the driver's braking energy as pure rotational motion. Push a button on the steering wheel and that disc dumps its energy back into the drivetrain for a 80-horsepower boost. This was the Flybrid KERS — and it worked by essentially turning the car into a mechanical battery.
Kinetic Energy Recovery Systems (KERS) come in several flavors: electrical (the now-familiar hybrid car approach), hydraulic (used in garbage trucks, of all things), and mechanical — the flywheel. The flywheel version is the most physically elegant: instead of converting kinetic energy to chemistry and back (losing energy at every step), you keep it as motion the entire time. Round-trip efficiency can exceed 70%, compared to roughly 30-40% for battery systems in the same duty cycle.
Here's the wild engineering. To store meaningful energy in a small package, the flywheel must spin absurdly fast — and kinetic energy scales with the square of angular velocity. Flybrid's 5 kg carbon-fiber disc at 64,500 RPM stores about the same energy as a 40 kg lead-acid battery. But at those speeds:
- Air resistance would melt the disc, so it lives in a vacuum chamber
- Standard bearings would incinerate, so it rides on magnetic bearings or ultra-precise ceramic ones
- If the containment fails, the disc becomes a frag grenade — hence the carbon-fiber composite, which shatters into fluff rather than shrapnel
The gyroscopic forces are also fascinating. A spinning flywheel resists changes in orientation — meaning a car with a large horizontal flywheel would fight against turning corners. Formula 1 teams mounted them vertically along the car's axis, and even then had to account for handling changes. Some designs use counter-rotating pairs to cancel gyroscopic torque entirely.
You've probably encountered this technology without knowing it. London buses use flywheel KERS to recover braking energy, cutting fuel use by around 20%. Volvo experimented with a rear-axle flywheel that let the front-wheel-drive engine shut off entirely at low speeds — turning any car into a temporary hybrid without needing a battery pack. And Porsche's 911 GT3 R Hybrid used a flywheel spun by an electric motor, then wired back through electric motors on the front wheels — a mechanical/electrical hybrid of hybrids.
The deepest irony? Flywheel energy storage is ancient. Potter's wheels are flywheels. Steam engines used massive iron flywheels in the 1700s. What changed is materials science: carbon-fiber composites can survive stresses that would tear steel apart, letting modern flywheels store orders of magnitude more energy per kilogram than their Victorian ancestors. The technology didn't get invented — it just got fast enough to matter.
Daily YT Documentary
Living in Saba | How Life Works on an Island with Almost No Flat Land | 4K Travel Documentary
2026-09-12

Channel: Remote Earth Journeys (4770 subscribers)
Saba is a five-square-mile volcanic peak jutting out of the Caribbean, and this documentary treats it as a genuine engineering and human-geography puzzle rather than a travel postcard. With almost no flat ground, every element of ordinary life — roads, homes, water collection, cemeteries, even the world's shortest commercial runway — has to be negotiated with the slope.
What makes this worth watching is how the film connects terrain to daily behavior. You see why houses are terraced up the mountainside, why rainwater cisterns replace groundwater wells (there are no rivers or aquifers), and how the famous switchback road called simply "The Road" was hand-built by a local named Josephus Lambert Hassell after Dutch engineers declared it impossible. The airstrip at Juancho E. Yrausquin — 400 meters bracketed by cliffs on three sides — gets a clear-eyed look at why pilots need special certification to land there.
The pacing favors explanation over scenery: interviews with residents about hurricane preparation, medical evacuation logistics, and the tight social fabric of roughly 1,900 people who all know each other. It's a solid case study in how geography constrains and shapes a small society, useful for anyone interested in island infrastructure, vernacular architecture, or the practical realities of extreme terrain.
Daily YT Electronics
I Built a Portable Dremel for Just $2! 🔥 Full Build & Test | DIY Mini Rotary Tool – Part 2
2026-09-12
Channel: DIY Maker Garage (1270 subscribers)
Most of today's crop leans heavily on hashtag-spam Shorts and vague "amazing project" clickbait, so a Part 2 build video that promises actual testing is a welcome outlier. This entry finishes a scratch-built portable rotary tool assembled from salvaged/cheap parts — the kind of small-motor project that teaches practical skills you can transfer to dozens of other builds.
Expect coverage of the mechanical coupling between a small DC motor and a collet or chuck (the trickiest part of any homemade Dremel clone), battery selection and mounting, switch wiring, and enclosure assembly. The "Full Build & Test" framing suggests the maker will actually push the tool with cutting, sanding, or engraving loads — which is where cheap DIY rotary tools usually reveal their weaknesses (torque droop, runout, overheating, coupling slip).
Watch for: how they solve shaft-to-bit alignment, whether they use a proper collet or an improvised chuck, and how the motor holds up under sustained load. If you missed Part 1, the two together make a decent case study in low-budget tool-making — a genre where the failure modes teach as much as the successes.
Caveat: the emoji-heavy title is a mild red flag, but the "Part 2 / Full Build & Test" structure and reasonable description suggest a real long-form build rather than a Short.
Daily YT Engineering
Patterned Steel: The Damascus Metallurgy
2026-09-12

Channel: Materials That Changed Everything (170 subscribers)
Damascus steel occupies a strange place in metallurgy — half legend, half genuine materials science mystery. This video from a tiny channel (170 subscribers) takes the serious route, digging into the wootz crucible process: the high-carbon ingots produced in South India and traded across the medieval world, and the specific conditions that gave the finished blades their characteristic banded surface pattern.
What makes this worth watching over the dozens of blacksmith-hype videos on the same topic is the focus on verified mechanical properties rather than folklore. The episode walks through what modern metallography has actually found in surviving wootz blades — the role of cementite (Fe₃C) segregation into aligned bands during slow cooling, trace impurities like vanadium that appear to catalyze the banding, and why the technique was effectively lost when the specific ore sources were exhausted.
It also situates the steel historically: the trade routes from Hyderabad to Damascus, why the finished-blade markets clustered where they did, and how the pattern-welded "Damascus" that modern smiths make is metallurgically a different beast from the original crucible steel. Good grounding for anyone who's watched the flashier Damascus content and wanted the actual science underneath.
Daily YT Maker
Laser Cutting a Roll-Top Wooden Box | ForgePrint 3D
2026-09-11
Channel: ForgePrint 3D (0 subscribers)
Note: this batch of candidates is unusually weak — mostly SVG file promos, shorts, and product demos. This video is the least-bad pick because it at least shows a real fabrication project rather than a marketing clip.
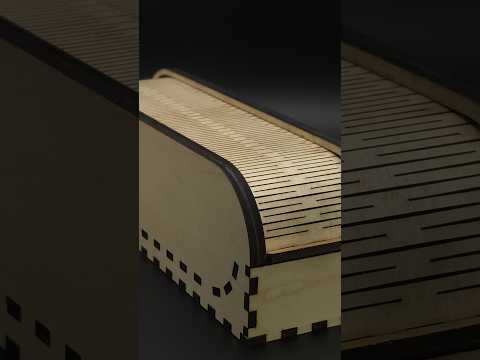
A roll-top box (think classic bread box or tambour-door desk organizer) is a surprisingly tricky object to fabricate. The tambour slats have to be uniform, aligned, and flexible enough to curl around a track cut into the side panels — which means the side-panel groove geometry is the whole ballgame. Get the radius wrong and the slats bind; get the slot width wrong and they rattle or fall out.
This behind-the-scenes clip from ForgePrint 3D shows the laser-cutting stage of that build on a Bambu Lab H2D — a machine most people know as a 3D printer, but which ships with an optional laser module. Watching a hybrid tool tackle a genuine woodworking job is worth a few minutes if you're curious about where these all-in-one desktop fab machines actually land in practice.
Zero subscribers means this is a brand-new channel, so the video is short on narration, but the parts on the cutting bed tell the story: nested slats, side panels with curved tambour tracks, and box joinery all laid out for efficient sheet use.
Daily YT Welding
I Made a Teddy Bear Name Plate for Sofia | Inkscape + ArcDroid CNC Plasma
2026-09-11

Channel: 6.8liter (995 subscribers)
This one stands out from a batch that's otherwise heavy on hashtag-spam shorts and product-link affiliate reviews. The creator walks through a complete small project from digital design to finished steel part, using two accessible tools that a lot of hobbyists are curious about: Inkscape for vector design and the ArcDroid portable CNC plasma system.
What makes it educational is the full pipeline view. Viewers get to see how a hand-drawn or reference image becomes a clean SVG suitable for plasma cutting — tracing, node cleanup, and the sizing/kerf considerations that separate a design that looks right on screen from one that actually cuts cleanly in steel. Then the ArcDroid side shows real-world CNC plasma work at a scale that fits in a home garage, which is a very different beast from the big industrial tables most videos showcase.
The sentimental framing (a name plate for his granddaughter) is a nice hook, but the real value is watching a maker demonstrate an approachable end-to-end workflow: design software → CAM prep → machine setup → cut → cleanup. If you've been eyeing an entry-level plasma CNC or wondering whether Inkscape is enough software to get started, this is a useful reference project.
